Collection built for your sources
We assess access paths, locations and pagination for each website or mobile app, then build collection around the records you need.
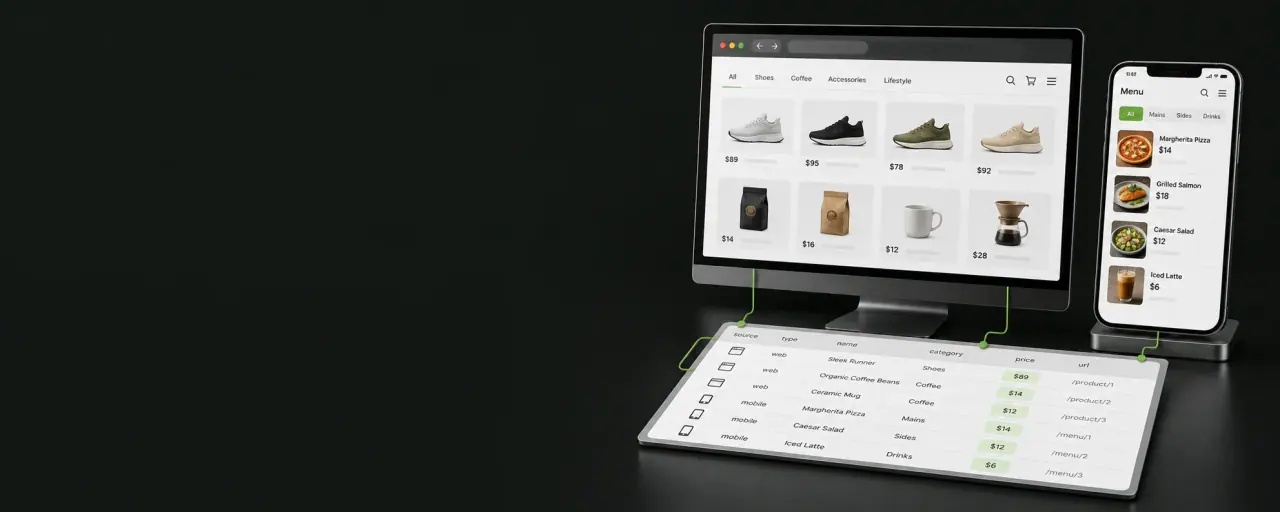
Managed data collection / ScrapingBuddy
Your sources. Your fields. Your schedule.
We build and maintain the collection, so your team can work with the data.
A daily operation maintained for 2+ years.
Read the case study Restaurant intelligence42Restaurant brandsBrand coverage within one restaurant data programme.
Read the case study Data engineering4-5 hrsProcessing, down from 3+ daysThe processing stage of a weekly restaurant data workflow.
Read the case studyThe deliverable
Compare prices, track inventory, research markets or update internal systems. We agree the dataset scope around your goal.
Explore data sourcesKeep the item, its location
and its price connected.
The work behind the dataset
For teams that need source-specific data, recurring coverage, or help maintaining a collection workflow.
See our quality and maintenance approachWe assess access paths, locations and pagination for each website or mobile app, then build collection around the records you need.
We normalise and deduplicate records without losing source-specific detail, keeping identifiers, currencies, sizes and locations connected in the output.
We check required fields, types, coverage and freshness against the agreed scope. Missing values and partial results should stay explicit, never filled with guesses.
For recurring projects, we agree reporting and handling of source changes, missing records and delivery issues, including maintenance and recovery scope.
From brief to delivery
Send website URLs or app names, the data you need and how you plan to use it. Tell us whether you need a one-off dataset or recurring collection.
We review feasibility and available capacity, then agree scope, pricing and timing. Any sample or pilot is agreed separately.
We implement and validate against the approved requirements. Recurring delivery and maintenance follow the agreed scope.
We can discuss a sample or pilot as part of the project review. Its fields, coverage, cost and acceptance criteria are agreed separately before that work starts.
The sources, access requirements, record volume, markets, refresh frequency and processing all affect the work. We review those requirements and our available capacity, then agree pricing and timing before accepting the project.
Share the app name or store link and the data you need. We assess the collection method and access requirements for that source. Account-based work is limited to accounts and data you are authorised to access; feasibility is reviewed before any delivery commitment.
Attribute extraction, classification, entity matching and summaries can be scoped alongside collection. We distinguish AI-derived fields from source facts and agree validation rules and additional costs before including them.
Your next data project
Share the websites or mobile apps and the data you need. We review feasibility and available capacity before discussing scope, delivery and pricing. Work starts only after both sides agree.
We review feasibility and available capacity before accepting a project. Scope, pricing and timing are agreed individually.
Your work email, project requirements, any first and last name or company you provide, and a label identifying this form are sent through Resend, our email delivery service, to our enquiry inbox. We use these details to review your project and respond, with your work email as the reply address.
Do not include passwords or API keys. Discuss confidentiality requirements with us before sending sensitive material.